Predictive Maintenance AI: A Practical Guide for Manufacturers
How manufacturers can use predictive maintenance AI to reduce unplanned downtime: which assets to start with, what data you need and how to scale.
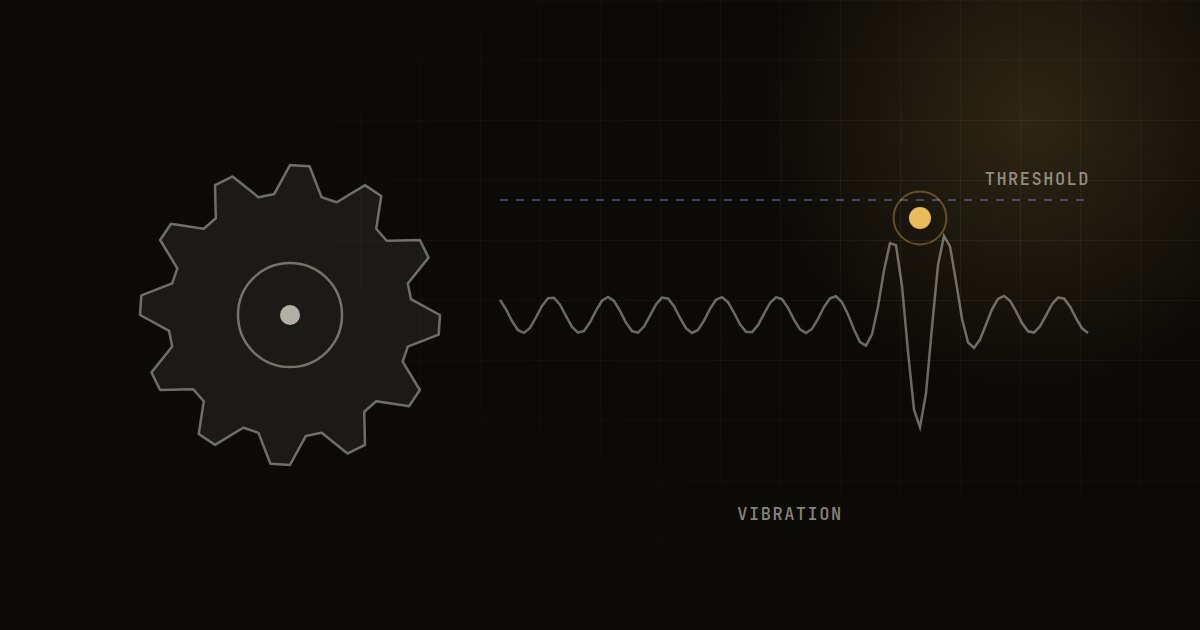
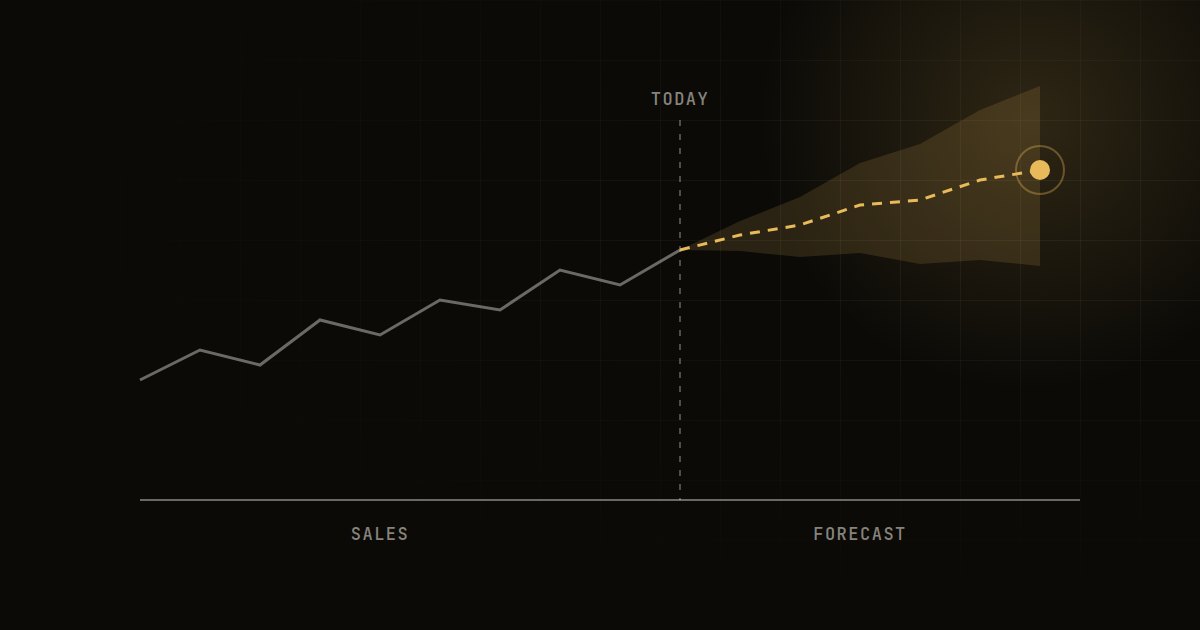
Predictive maintenance AI uses sensor, machine and maintenance data to predict when equipment is likely to fail, so teams can intervene before a breakdown. It works by learning normal operating patterns from signals such as vibration, temperature, current and pressure, then flagging anomalies or estimating remaining useful life. The payoff is less unplanned downtime and better planned maintenance.
It sounds simple, and the core idea is. The hard part is everything around the model: getting reliable data off the shop floor, choosing the right assets, earning the trust of maintenance engineers and building alerts they actually act on. This guide covers each of those, based on what we see work in real plants.
Reactive, preventive and predictive maintenance compared
Most plants use a mix of approaches. Predictive maintenance does not replace the others; it improves decisions for the assets where failures are costly and signals are available.
| Approach | How it works | Strengths | Weaknesses |
|---|---|---|---|
| Reactive | Fix it when it breaks | No upfront effort, fine for cheap non-critical assets | Unplanned downtime, secondary damage, safety risk |
| Preventive | Service at fixed intervals or run hours | Simple, predictable planning | Replaces parts that are still healthy, misses early failures |
| Condition-based | Act when a measured value crosses a threshold | Uses real asset condition | Thresholds are static and often catch problems late |
| Predictive (AI) | Models detect patterns that precede failure | Earlier warning, fewer false alarms when tuned well | Needs data, integration and ongoing model care |
A practical rule of thumb: if an asset is cheap, redundant or quick to replace, preventive or reactive maintenance is usually fine. Save predictive maintenance AI for critical, expensive or bottleneck equipment.
How predictive maintenance AI works
Data sources
The richer and more consistent the data, the better the predictions. Typical inputs include:
- Condition signals: vibration, temperature, acoustic, current draw, oil quality, pressure and flow.
- Operating context: load, speed, product being run, shift and ambient conditions. Without context, a model may flag a normal change in production as an anomaly.
- Control system data: PLC and SCADA tags, alarms and events, often available through a historian.
- Maintenance history: work orders, failure codes and parts replaced from your CMMS or ERP. This is how you label what a failure looked like.
In many plants the maintenance history is the weakest link. Free-text work orders like "machine stopped, fixed" do not tell a model much. Cleaning and structuring this history is often worth doing before any modelling.
Model approaches
There is no single best algorithm. The right approach depends on how much failure history you have.
- Anomaly detection. Learns what normal looks like and flags deviations. Useful when you have plenty of healthy data but few recorded failures, which is common.
- Failure classification. Predicts whether a specific failure mode is likely within a time window. Needs labelled examples of past failures.
- Remaining useful life estimation. Estimates how long until an asset needs intervention. Needs good run-to-failure history, so it is usually a later-stage capability.
- Physics-informed and hybrid models. Combine engineering knowledge, such as bearing fault frequencies, with machine learning. These often perform better with limited data and are easier for engineers to trust.
Start with anomaly detection and engineering rules, then add supervised models as you accumulate labelled failures.
Edge versus cloud
High-frequency vibration data can be large. A common pattern is to compute features at the edge, near the machine, and send summarised data to the cloud for modelling and dashboards. Plants with limited connectivity or strict OT security policies may keep more processing on site. The trade-off is between central visibility and simplicity on one hand, and bandwidth, latency and security on the other.
A step-by-step rollout plan
- Pick the right assets. Rank equipment by cost of failure, downtime impact, safety and failure frequency. Choose a small group of similar assets, such as motors, pumps, compressors or gearboxes, for the pilot.
- Define the business outcome. Agree the metric up front: unplanned downtime hours, mean time between failures, maintenance cost or spares inventory. Record the current baseline.
- Audit existing data. Check what sensors exist, what the historian stores, at what frequency, and how reliable the maintenance records are.
- Fill sensor gaps. Retrofit wireless vibration and temperature sensors where needed. This is often quicker and cheaper than expected for rotating equipment.
- Build the data pipeline. Collect, time-align and store signals together with context and maintenance events. A sound data platform matters more than the choice of algorithm.
- Develop and validate models with engineers. Review flagged anomalies with maintenance staff. Their feedback labels the data and builds trust.
- Design actionable alerts. Every alert should say which asset, what is abnormal, how urgent it is and a suggested check. Route alerts into existing CMMS work order flows, not a separate dashboard nobody opens.
- Run in shadow mode. For a period, generate alerts without acting on them automatically, and compare against what actually happened.
- Go live and measure. Track alert precision, missed failures and the business metric against baseline.
- Scale and maintain. Extend to more assets and sites. Retrain models as equipment, products and operating conditions change, and monitor for drift. This is where solid MLOps practices pay off.
Costs and what drives them
Costs vary widely by scope, number of assets, existing instrumentation and integration needs, so any figure should be treated as indicative only. The main drivers are:
- Sensors and connectivity: minimal if you already have good instrumentation and a historian, significant if you need retrofits across many assets.
- Data platform and integration: connecting OT systems, historians and CMMS, often the largest engineering effort.
- Model development and validation: usually smaller than people expect, provided the data work is done well.
- Ongoing operations: monitoring, retraining, cloud or edge infrastructure and support.
As a rough guide, a focused pilot on a handful of asset types often runs for a few months, including a shadow period. The return depends mainly on how expensive your unplanned downtime is. A plant where one line stoppage is very costly will justify investment far faster than one with plenty of redundancy.
Common pitfalls
Too many alerts. A model that raises frequent false alarms is quickly ignored. Tune for precision on critical assets and let engineers adjust sensitivity.
Ignoring operating context. Changes in product, load or speed can look like faults. Include context in the features.
No link to action. Predictions that do not create a work order or a planned intervention deliver no value.
Treating it as an IT project. Maintenance and operations leaders must own the outcome. Data teams enable it.
Underestimating OT security. Connecting plant systems to cloud services needs careful network segmentation and access control, designed with your OT and security teams. Our managed services team often supports this layer.
Frequently asked questions
What is predictive maintenance using AI?
It is the use of machine learning on equipment sensor data and maintenance history to predict failures before they happen. Instead of servicing at fixed intervals or after breakdowns, teams intervene when the data shows early signs of a problem. It is typically applied to critical rotating and process equipment.
What data is needed for predictive maintenance?
You need condition data such as vibration, temperature or current, operating context such as load and speed, and maintenance records describing past failures and repairs. Data should be time-stamped and consistently collected. Poor maintenance records are the most common gap.
How accurate is predictive maintenance AI?
Accuracy depends on the asset, failure mode, sensor quality and history available, so there is no universal figure. Some failure modes, such as bearing wear on rotating equipment, give clear early signals, while others are harder to predict. Measure precision and missed failures on your own assets during a shadow period.
How long does it take to implement predictive maintenance?
A focused pilot on a few asset types typically takes a few months, including data preparation and a shadow period. Plants with good existing instrumentation and clean maintenance records move faster. Scaling across a site or multiple plants takes longer and should be phased.
Is predictive maintenance worth it for small manufacturers?
It can be, if you have a small number of critical or bottleneck assets whose failure is costly. Start with affordable retrofit sensors on those assets rather than a plant-wide programme. For non-critical equipment, preventive maintenance is often good enough.
How Sunday Labs can help
We help manufacturers build predictive maintenance AI that engineers trust and use: asset selection, sensor and data audits, OT-to-cloud pipelines, models and alerts integrated with maintenance workflows. Every engagement is staffed with senior engineers, so the people who design the system also build it. See our manufacturing and supply chain work, or start a conversation about your plant.