Test Automation Strategy: A Practical Guide for Growing Teams
What to automate, what to leave manual, and how to build a test suite your developers trust, with a step-by-step plan and the metrics worth tracking.
A good test automation strategy decides what to test, at which layer, with which tools and when tests run, so that the team gets fast, reliable feedback on every change. It favours many fast unit and API tests, fewer end-to-end UI tests, strict control of flaky tests, and metrics tied to escaped defects rather than test counts.
Most teams do not fail at automation because they chose the wrong framework. They fail because they automated the wrong things, at the wrong layer, and then stopped trusting the results. This guide sets out how we approach it with engineering leaders who want automation that actually protects releases.
Why most test automation efforts stall
The pattern is familiar. A team hires automation engineers, who write hundreds of UI scripts against the staging environment. Within a few months, a meaningful share of runs fail for reasons unrelated to the code: timing issues, test data collisions, a changed button label. Developers start ignoring red builds. The suite becomes expensive to maintain and nobody trusts it.
The root causes are usually structural:
- Too much testing through the UI, which is slow and brittle.
- No ownership: QA writes tests, developers break them, and nobody fixes them.
- Shared, unmanaged test data that makes tests depend on each other.
- Tests run too late, often nightly, so failures arrive long after the change that caused them.
- Vanity metrics such as "number of automated test cases" rather than defects caught.
A test automation strategy exists to prevent exactly these problems.
The building blocks of a test automation strategy
1. Decide the shape: pyramid, not ice cream cone
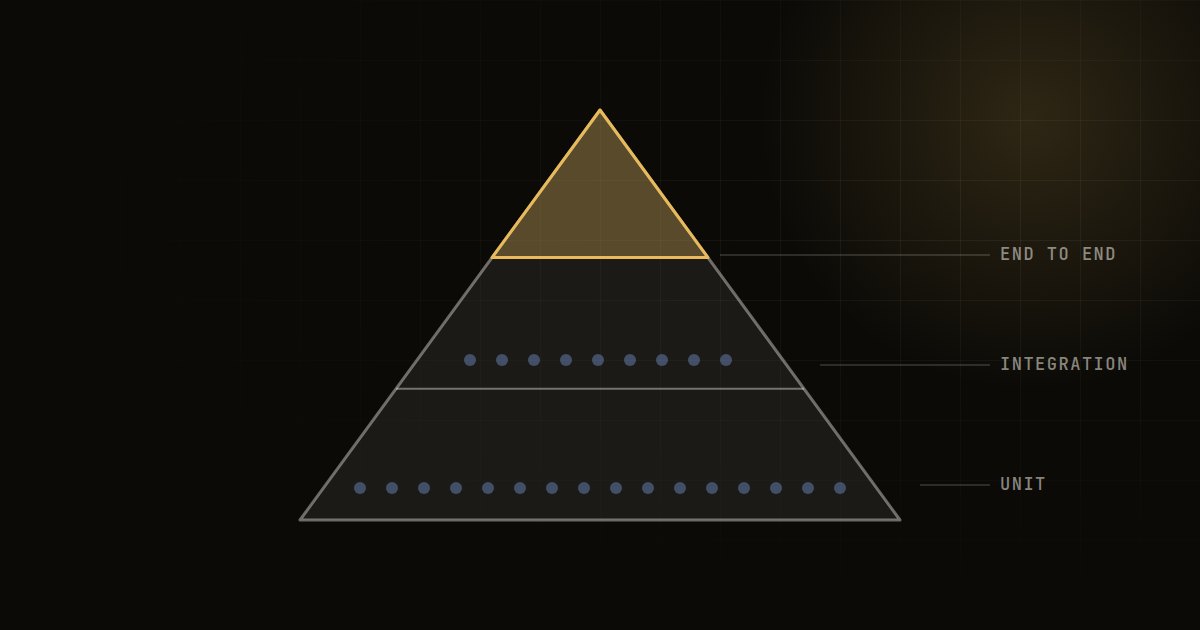
The test pyramid remains the most useful mental model. Put most of your automated checks at the bottom, where they are fast and cheap, and only a thin layer at the top.
| Layer | What it checks | Speed | Typical share of the suite | Owned by |
|---|---|---|---|---|
| Unit | Functions and classes in isolation | Milliseconds | Largest | Developers |
| Component and integration | Modules with real dependencies such as a database | Seconds | Substantial | Developers, with QA input |
| API and contract | Service behaviour and agreements between services | Seconds | Substantial | Developers and QA |
| End-to-end UI | Critical user journeys through the real interface | Minutes | Small | QA, with developer support |
| Exploratory and manual | Usability, edge cases, new features | Human pace | Targeted | QA |
The anti-pattern is the "ice cream cone": few unit tests, a thick layer of manual and UI tests on top. It feels thorough but gives slow, unreliable feedback.
2. Choose what to automate first
Not everything deserves automation. Prioritise tests that are run often, cover high-risk areas and have stable expected behaviour. A simple scoring approach works well:
- Business impact if broken: payments, login, checkout, data exports and anything regulatory score highest.
- Frequency of change: code that changes often benefits most from regression protection.
- Stability of the feature: automating a screen that is being redesigned next month is wasted effort.
- Cost of manual execution: long, repetitive regression checks are prime candidates.
- Defect history: areas that have produced production incidents deserve extra coverage.
Leave genuinely exploratory work, visual judgement and one-off checks to skilled manual testers. Automation complements human testing; it does not replace it.
3. Pick tools that fit your stack and team
Tool choice matters less than people think, but a few principles help:
- Prefer tools in your application's language for unit and integration tests, so developers write and maintain them naturally.
- For web UI testing, modern frameworks such as Playwright or Cypress offer auto-waiting and better debugging than older approaches. Selenium remains viable, particularly where you already have investment.
- For APIs, use code-based tests in your main language or a dedicated tool, and add contract testing (for example Pact) when multiple teams own services that talk to each other.
- For mobile, Appium, Espresso and XCUITest each have trade-offs around speed and cross-platform reuse.
- For performance, tools such as k6, JMeter or Gatling belong in the strategy too, run on a schedule and before major releases.
Standardise on as few tools as you can. Every extra framework is another thing to maintain, upgrade and teach.
4. Treat test data as a first-class concern
Unreliable test data causes more flaky tests than any framework. Good practice includes:
- Each test creates the data it needs and cleans up afterwards, or runs against an isolated, disposable environment.
- Use factories or builders rather than hand-maintained fixtures.
- Never use real customer data in lower environments. Use synthetic or properly masked data, particularly in regulated sectors such as financial services or healthcare.
- Seed reference data through scripts in version control, not manual database edits.
5. Integrate tests into CI/CD from day one
Tests that do not run automatically on every change are documentation, not protection. A practical layering looks like this:
- On every commit or pull request: unit tests, linting, static analysis and fast integration tests. Target a feedback time developers will actually wait for, ideally under ten minutes.
- On merge to main: API and contract tests, plus a small smoke suite of end-to-end tests.
- Before release or nightly: the full end-to-end regression suite, performance tests and security scans.
- After deployment: synthetic monitoring of critical journeys in production.
Our CI/CD best practices guide covers pipeline design in more depth.
Dealing with flaky tests
A flaky test passes and fails without any change to the code. It is the single fastest way to destroy trust in automation. Handle flakiness with a clear policy:
- Detect it. Track pass and fail history per test, and flag any test that fails and then passes on retry.
- Quarantine it. Move flaky tests out of the blocking pipeline immediately, into a separate, visible quarantine suite.
- Fix or delete it within a set period, such as one or two sprints. A test that stays quarantined forever is dead weight.
- Find the root cause. Common culprits are fixed sleeps instead of waits, shared data, test order dependence and unstable third-party services that should be stubbed.
- Limit automatic retries. One retry can mask real intermittent bugs. Use retries as a diagnostic tool, not a permanent fix.
Metrics that tell you whether the strategy works
Avoid counting test cases. Track outcomes instead:
- Escaped defects: bugs found in production that tests should have caught. This is the most honest measure.
- Pipeline feedback time: how long developers wait for a result on a pull request.
- Flaky test rate: the proportion of failures not caused by code changes.
- Change failure rate: the share of deployments that cause an incident or rollback.
- Automation maintenance effort: time spent fixing tests versus writing new ones.
Review these monthly. If escaped defects cluster in one area, that is where your next automation investment should go.
Roles and ownership
The most effective teams make quality a shared responsibility. Developers own unit, integration and most API tests as part of their definition of done. QA engineers act as quality coaches and specialists: they design risk-based test plans, build the end-to-end framework, run exploratory testing and watch the metrics.
A typical scenario: a SaaS company with a ten-person product team and one QA engineer running a two-day manual regression before each release. Moving to this model usually means the developers add API tests for each new endpoint, the QA engineer automates the dozen most critical journeys end to end, and the manual regression shrinks to focused exploratory sessions. Releases become smaller and more frequent because the safety net is faster.
A 90-day starting plan
- Weeks 1 to 2: audit current tests, map critical user journeys and list recent production incidents.
- Weeks 3 to 4: agree the pyramid targets, pick tools, set up test data management and wire the first suites into CI.
- Weeks 5 to 8: automate the highest-priority API tests and the top five to ten critical UI journeys.
- Weeks 9 to 12: introduce flaky test tracking, dashboards for the metrics above and a quarantine policy.
After that, grow coverage where escaped defects and risk point you, not where it is easiest.
Frequently asked questions
What is a test automation strategy?
It is a documented plan for which tests to automate, at which layer, with which tools, who owns them and when they run in the delivery pipeline. It also defines how you handle test data, flaky tests and measurement. Without one, automation tends to grow in the easiest direction rather than the most valuable.
What should not be automated?
Exploratory testing, usability judgements, features that are about to change significantly and one-off checks are usually better done manually. Tests that would take longer to build and maintain than to run by hand over their lifetime are also poor candidates.
How much test coverage is enough?
There is no universal number, and chasing a coverage percentage often produces low-value tests. Aim for strong coverage of business-critical and frequently changed code, and use escaped defects to find gaps. Code coverage is a useful signal of untested areas, not a goal in itself.
Should developers or QA write automated tests?
Both. Developers should write unit, integration and most API tests as part of normal work. QA engineers are best placed to design risk-based end-to-end coverage, maintain the UI framework and run exploratory testing.
How long does it take to build a reliable automation suite?
A focused team can have meaningful API and critical-journey coverage running in CI within roughly three months. Building a mature, trusted suite across a large product usually takes longer and is an ongoing practice rather than a one-off project.
How Sunday Labs can help
Sunday Labs provides QA and test automation as part of our managed services, from strategy and framework design to running regression suites inside your CI/CD pipeline. Engagements are led by our founder and delivered by senior engineers who have built test infrastructure for high-traffic products, so the focus stays on catching real defects rather than growing test counts. If your releases feel slower or riskier than they should, start a conversation with us.